When a peptide references a monomer that Ideation cannot resolve, that peptide is imported with its HELM sequence preserved but without a full structure or calculated properties, and the dataset is flagged. This guide shows how to see what is missing, export the list, register the missing monomers, and sync the dataset — either the peptides that were blocked, or every peptide once a monomer's definition changed.
Step 1: Spot the import issues
Wherever a dataset with import issues appears, an amber warning triangle appears with it. Hover it to read what happened — "N structures imported with missing data", for example; click it to open the details.

You will find the same warning in several places, all opening the same dialog:
- the dataset title bar, left of your role;
- the dataset settings drawer, on the Details tab next to the Source;
- the SAR report title bar;
- dataset cards on the Home and project pages.
In the import wizard and on the import status page it appears instead as a banner stating what happened — "N structures imported with missing data.", "N structures could not be imported." or, for a mix, a breakdown such as "22 import issues: 19 imported with missing data, 3 monomers not registered." — with a View Details link.
In the grid, affected rows are highlighted and a Missing Monomers column lists the unresolved monomer(s) the row uses: a residue by its symbol (Zzz1), a chemical object with its polymer type (CHEM Zzz1). Monomers whose symbol is malformed, which no registration can fix, are listed there too. Those rows keep their HELM and their monomer drawing but show 0 atoms and no computed properties. The column only exists while something is unresolved — it disappears once everything resolves.
Step 2: Read the reasons
The dialog's title states what happened — or, when there are issues of several kinds, how many there are ("4 import issues"), with the kinds on the first line ("2 peptides imported with missing data, 2 monomers not registered.") — and its entries are grouped by what it means for your data:
- Peptides not imported — structures that are not in the dataset at all, such as a record the file parser could not read.
- Peptides imported with missing data — structures that are in the dataset and usable, with some of their data missing. Each entry says what: chem chains, branches and bridges when no structure detail could be built, molecular weights, atom count, canonical SMILES, InChI String and InChI Key when no V2000 could be produced, CTAB v3000, or monomer count. A peptide with a missing monomer is listed here: it keeps its backbone sequence and gets the rest once the monomer is registered and the dataset synced.
- Monomers not registered — every monomer the dataset uses that Biotoolkit Monomers does not have, and the monomer templates of an SDF that could not be read or registered, with the reason (see below).
- Reported at import — entries of datasets imported before this distinction was recorded; whether those structures are in the dataset is not known.
Above the list, the dialog can also show warnings that are not about one peptide: the columns of your file that Ideation computes itself and did not import, a formula column the last Sync monomers could not recompute, or a last sync that failed and changed nothing.
Each entry shows the primary identifier, the reason, and what is missing when that was recorded, under a Missing data line. A coloured Severity line says how much the entry matters for your SAR analysis:
- In orange, a warning: the peptide is imported and usable, but some of its data is missing, such as molecular weights, atom count, canonical SMILES, InChI and InChIKey, CTAB v3000 or monomer count. It can still be fully used in SAR analysis.
- In red, an error: the peptide is not imported at all, or it is imported with chem chains, branches and bridges missing, so only its backbone is available in SAR slides. Fix these first.
Monomer entries have no severity (the peptides that use them are listed as errors), and neither do entries from datasets imported before this detail was recorded.
Each monomer Biotoolkit Monomers does not have is listed under Monomers not registered as Monomer "X" (PEPTIDE, library) or Monomer "X" (CHEM, library), with the reason: not found in Biotoolkit Monomers for a monomer missing from your organization's monomer library, or the service's reason when it refused a monomer template of your SDF — invalid chemistry, a name already used by another monomer, a deleted monomer with the same structure, a template that could not be built. Datasets imported with a monomer library file, which a CSV or Excel import accepted before the 12 November 2026 release, can also list the rows of that file that could not be read, giving the row's cause first, then the service's, for example no smiles or ctab; without a structure it can neither be registered nor rendered; not found in Biotoolkit Monomers, or as an entry of their own, Monomer "X" (library row N). These entries appear only when a peptide of the dataset uses that monomer. The peptides built from it appear in the same list as missing it, so the monomer entry is the explanation of those peptide entries. See How to Create a Peptide Dataset.
Export CSV, at the top of the list, downloads the whole list as structure-issues.csv with one row per entry: the source (dataset, or monomer library for a monomer entry), the identifier (peptide ID or monomer symbol), the outcome (not imported, imported with missing data, not registered for a library row, not recorded for an entry from before outcomes were tracked), the severity (error or warning, empty for library rows and legacy records), the missing data, the structure as written in your file (the peptide's HELM or the monomer's SMILES) and the error. It is the quickest way to fix a large file at the source and re-import it.
Entries written before this release carry no structure, so their structure cell is empty until the dataset is re-imported or synced.

Not every entry is a missing-monomer case, and the distinction decides what you can do about it.
Missing-monomer reasons always take the same shape:
HELM sequence preserved. Missing monomers: Zzz1 (not found in Biotoolkit Monomers). Register missing monomers in Biotoolkit Monomers, then sync this dataset to get the full structure and calculated properties.
The symbols are grouped by cause, and the cause in parentheses tells you why that particular symbol did not resolve:
| Cause | Meaning |
|---|---|
not found in Biotoolkit Monomers |
The symbol is unknown and no structure was available to register it. Register it (Step 3). |
conflicts with existing public symbol "X" or conflicts with existing private symbol "X" |
The structure is already registered under symbol X in a way that cannot become an alias, for example in the public library. Use X in your file. |
its name "N" is already used by "X" |
The monomer's name N (not its symbol) is already used by monomer X of the same polymer type: a name is used once per type. Change the name of the monomer in the monomer template of your SDF, and import again. |
same structure as a monomer of the library, but its name is already used by "X" |
The structure is already registered, but your symbol is already a name of another monomer (X), so it cannot become a second name of this one. Rename the monomer in your file. |
matches a deleted monomer of the library: restore it in Biotoolkit Monomers or rename it |
The structure, or the symbol, is that of a deleted monomer; when the service names it, the cause reads … of the library ("X"): …. Restore it in Biotoolkit Monomers, or rename the monomer in your file. |
invalid chemistry: … |
Biotoolkit Monomers rejected the structure supplied for the symbol, for the reason that follows. Correct the structure in your file. |
invalid template: … |
The monomer template could not be built or was refused — for example rgroup_labels_mismatch (its R-group labels don't match), no_rgroups, or template declared as CHEM, used as PEPTIDE (your file declares the monomer under another polymer type than the chain that uses it). client_bug is an Ideation problem: register the monomer by hand and sync. |
invalid symbol format: a symbol is 1 to 50 characters with no space, so it cannot be registered |
The symbol itself is malformed: no registration or sync can fix it. Rename the monomer in your file and re-import. |
template conversion failed |
The supplied structure could not be converted into a monomer template. |
Biotoolkit Monomers rejected it (HTTP N): … |
Biotoolkit Monomers answered with an error Ideation does not recognize; what follows is the service's own message. |
unexpected Biotoolkit Monomers answer (HTTP 200): … |
Biotoolkit Monomers answered, but in a form Ideation could not read. Register the monomer by hand and sync; if it keeps happening, contact support. |
Biotoolkit Monomers unavailable |
A transient service problem for that symbol. Sync again later. |
A symbol can name a residue and a chemical object (CHEM) with different structures, so a missing CHEM monomer is named with its type, CHEM Zzz1, and only the peptides that use it as a chemical object are affected. The message ends with what to do: "Register missing monomers in Biotoolkit Monomers, then sync this dataset to get the full structure and calculated properties." when registering is the fix (not found in Biotoolkit Monomers, template conversion failed, invalid template: client_bug, Biotoolkit Monomers rejected it …, unexpected Biotoolkit Monomers answer …, Biotoolkit Monomers unavailable), or "Correct the monomers above as their reason says, then import the dataset again." for every other cause. A peptide missing one monomer of each kind gets both.
Structural / HELM reasons are problems in the peptide itself and registering a monomer will not fix them — the HELM has to be corrected at the source and the dataset re-imported. HELM Rules for Peptide Import lists the rules a HELM must follow. For example:
- "PEPTIDE1,CHEM1,30:R3-1:R1 is not valid: Attachment point R3 for monomer source
Dap_Acdoesn't exists" - "HELM conversion failed: Unknown attachment point 'R2' in monomer …"
- "No KET representation could be produced from V3000 or HELM"
A peptide is never reported twice. If it is listed because of a missing monomer, Ideation does not also report a generic conversion failure for it.
Biotoolkit Monomers runs a duplication check on structure, so a monomer may already be registered under a different symbol. In that case Ideation registers your symbol as an alias of the existing monomer instead of registering a duplicate — which is why a symbol can resolve even though you never registered that exact name. The alias belongs to your organization and to the polymer type it is used with (a symbol can name a residue and a different chemical object), it is listed with the monomer in Biotoolkit Monomers, and your peptides keep the symbol you wrote.
Step 3: Register the missing monomers
If Biotoolkit Monomers still reports monomers as missing, the dialog ends with a highlighted box naming them:
The following monomers are not registered in Biotoolkit Monomers: Zzz1. Register them in Biotoolkit Monomers, then click "Sync Monomers" button to synchronize. It will recompute structures and properties.
If you cannot edit the dataset, the box ends with "someone who can edit this dataset can then sync them." instead. Monomers with a malformed symbol are not in the box: no registration can fix them.
Open the Biotoolkit Monomers link, which opens Biotoolkit Monomers for your organization, and register each listed monomer with its symbol, polymer type and structure: a monomer listed with its type, such as CHEM Zzz1, with the CHEM polymer type, any other with the PEPTIDE polymer type. Then return to Ideation.
This box only appears while the service actually reports something missing. A dialog that lists only structural failures, or whose monomers have since been registered, shows no sync action. While Ideation is checking you will briefly see "Checking for missing monomers…"; if the check itself fails it says "Could not load the list of missing monomers, so it is not known which ones still need registering."
Once a non-natural monomer is in Biotoolkit Monomers, every current and future dataset that uses the same symbol resolves it automatically — you never need to register it again. Only an SDF import can change a monomer of your organization's library: when its template has the same symbol but another structure, the monomer is updated and Biotoolkit Monomers keeps its previous version. Public monomers are never changed.
Step 4: Sync the dataset
There are two ways to sync, and they do not recompute the same peptides.
From the dialog — the blocked peptides only. Back in the dialog, click Sync monomers; it is offered only if you can edit the dataset, otherwise the dialog still lists the missing monomers. Ideation re-resolves the dataset's still-missing monomers against the service and, for any that are now available, recomputes the structure and properties of the peptides that were blocked. Peptides that imported fine are not touched. When no monomer is missing but some peptides were imported with data missing (even only a monomer count), the dialog offers the full sync below instead: a conversion can fail because of how a monomer is defined (its structure, stereo or cap groups), and once you correct that monomer, only a full sync rebuilds those peptides.
From the dataset title bar — every peptide. The Sync monomers icon (the circular arrows, right of the Ready status) is available on every peptide dataset you can edit, whether or not anything was reported. It rebuilds all the dataset's peptides from their HELM: monomers are resolved again, structures (KET, V3000, V2000, SMILES) are converted again, and the computed columns (molecular weights, atom count, InChI String, InChI Key) are filled again, along with the formula columns that use them. Use it after a monomer was corrected in Biotoolkit Monomers — its cap groups, its structure — since such a change alters the chemistry of peptides that had imported without a problem. A confirmation dialog states what will happen before anything starts; the icon is disabled while the dataset is being processed.

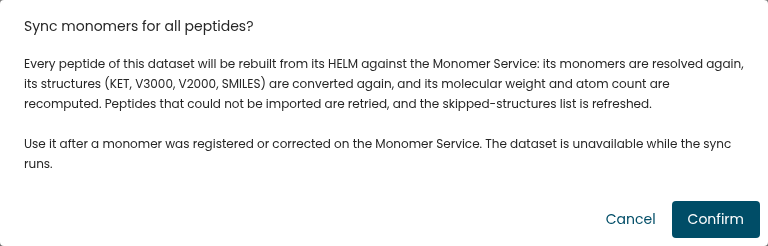
Peptides that could not be converted are retried as well, and the issue list is refreshed the same way as below — including peptides that fail for the first time, which join it.
You will get one of three responses:
| Message | Meaning |
|---|---|
| Monomer synchronization started. | The background job is running. |
| The dataset is not ready to synchronize. Please try again shortly. | The dataset is busy — for example a sync is already running. Nothing was started; retry in a moment. |
| Error syncing monomers. … | The request itself failed. |
The sync runs in the background. On a dataset large enough for it to take a while, the dialog follows along: its title changes to Synchronizing Monomers, the issue list is replaced by a live progress timeline — Initializing → Synchronizing Monomers → Recomputing Peptides → Ready — with an "N / M structures recomputed" progress bar. You can close the dialog at any time; the work continues.
When it finishes:
- peptides that now resolve are removed from the issue list, so the warning count drops (and the warning disappears entirely once the list is empty);
- a Monomer "X" (PEPTIDE, library) or Monomer "X" (CHEM, library) entry is removed too once Biotoolkit Monomers knows that monomer, since the peptides it explained now convert; a Monomer "X" (library row N) entry once the service knows the symbol under every polymer type the dataset uses it with;
- peptides still missing a monomer keep a refreshed reason, so the causes you read are always current;
- peptides that fail for a structural reason keep their entry, with a refreshed reason when they were recomputed;
- after a full sync, a peptide that fails for the first time is added to the list, with its HELM.
Syncing is always user-initiated — Ideation never auto-syncs.
The sync ends without changing anything and the dataset returns to Ready; you are not notified separately. The unreachability shows up as Biotoolkit Monomers unavailable in the per-peptide reasons, or as "Could not load the list of missing monomers, so it is not known which ones still need registering." in the dialog. Retry once the service is back.